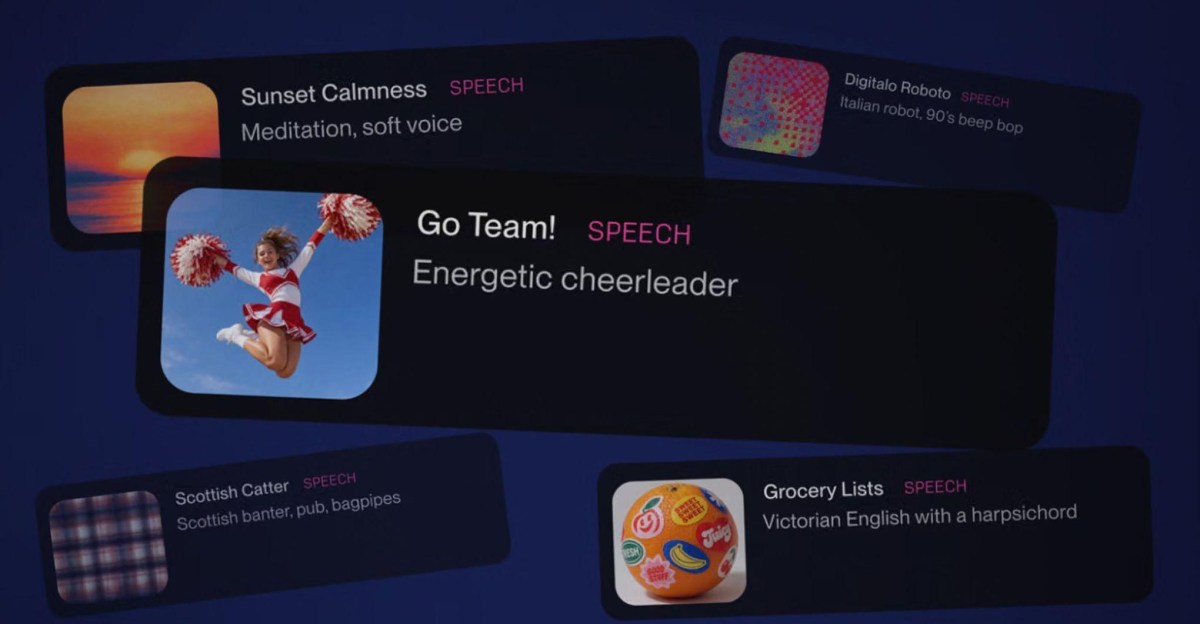

Suno Expands AI Capabilities with New Speech Feature
Suno has taken a significant step beyond its roots in AI music by introducing an innovative feature aimed at generating spoken voices from written scripts or descriptive prompts. This new capability, known as Speech, is currently available in public beta on both web and mobile platforms, allowing users to create voiceovers paired with complementary background music.
“Music will always be at the heart of Suno and what we build. At the same time, our vision has always extended to other forms of human expression,” stated Jack Brody, the chief product officer of Suno, in a recent announcement. Brody emphasized that the incorporation of Speech marks a pivotal expansion of the platform’s capabilities: “Today, we’re expanding what’s possible in Suno with Speech: the first audio model that generates voice and music together as one cohesive track.”
Although AI-generated speech is not a new phenomenon—DeepMind has been developing deep learning speech synthesis for the past decade, and companies like Adobe and ElevenLabs have made their own strides in text-to-speech technology—Suno’s entry into this space seeks to diversify its offerings amidst a backdrop of legal challenges related to its music generation tools.
The unique aspect of Suno’s Speech feature is its integration of AI-generated music and voice, which presents a fresh take on standard text-to-speech utilities. Users can easily toggle off the background music if they prefer a straightforward speech output. This flexibility allows for various applications, such as pairing soothing music with poetry or energizing tracks for persuasive speeches and dynamic voiceovers.
To utilize the Speech feature, users can navigate to the “Create” tab and select the Speech option. There are two operational modes available: the Simple mode, where users can describe their desired output through a prompt (e.g., “a pirate captain rallying his crew”), and the Advanced mode, which enables them to input a custom script directly. Furthermore, the advanced settings allow adjustments to the voice’s gender, speaking style, and voice variability. Each generated speech can have a maximum duration of approximately eight minutes.
While Suno acknowledges that the new feature is still in its early stages, Brody reassured users that improvements will be continuously made based on feedback. “Beta really does mean beta,” he remarked. “Occasionally, British accents can wander off to Australia and back. Dramatic pauses may be very dramatic. You will almost certainly discover uses for this that never occurred to us.”
Editor’s Take
This development is noteworthy as it marks Suno’s ambition to blend voice and music generation, offering users novel creative tools. Its flexibility could serve various industries, including media and entertainment, by enabling richer audio experiences. As this technology evolves, it holds potential benefits for developers looking to enhance their applications with innovative audio features.
Source: www.theverge.com